A new post on Apple’s Security Research blog details the fascinating tech, architecture, and thinking behind the iPhone 18 Pro’s new Reference Image camera mode. https://9to5mac.com/2026/0...

With Cybertruck, we introduced & scaled many automotive firsts
48V architecture: 4x lower current that enables thinner, lighter wiring
True Steer-by-Wire with no mechanical steering link, enabling variable steering response
Combined with rear-wheel steering, this also brought coordinated front + rear steering for greater low speed maneuverability & high speed stability
Structural stainless-steel exoskeleton: allows exterior panels to carry structural loads, resu https://x.com/Tesla/status...
48V architecture: 4x lower current that enables thinner, lighter wiring
True Steer-by-Wire with no mechanical steering link, enabling variable steering response
Combined with rear-wheel steering, this also brought coordinated front + rear steering for greater low speed maneuverability & high speed stability
Structural stainless-steel exoskeleton: allows exterior panels to carry structural loads, resu https://x.com/Tesla/status...

🐋 DeepSeek just made its AI architecture much cheaper
DeepSeek has introduced V4.1-Flash, a new multimodal model designed to deliver more intelligence while using dramatically less compute and memory.
The model has 552B parameters, but only 8B are active for input and 16B for output thanks to a new Causal Encoder–Decoder architecture. DeepSeek says its combination of new pre-training and large-scale RL can outperform even its flagship V4-Pro on several benchmarks.
The bigger breakthrough may be efficiency. V4.1-Flash uses just 1/4 of the HBM and 1/8 of the SSD storage needed for its previou
DeepSeek has introduced V4.1-Flash, a new multimodal model designed to deliver more intelligence while using dramatically less compute and memory.
The model has 552B parameters, but only 8B are active for input and 16B for output thanks to a new Causal Encoder–Decoder architecture. DeepSeek says its combination of new pre-training and large-scale RL can outperform even its flagship V4-Pro on several benchmarks.
The bigger breakthrough may be efficiency. V4.1-Flash uses just 1/4 of the HBM and 1/8 of the SSD storage needed for its previou

🚀 SpaceX is putting AI data centers in orbit
SpaceX is reportedly taking NVIDIA’s Vera Rubin architecture to space with its new Starmind satellites.
Each satellite could pack 72 Rubin GPUs + 36 Vera CPUs into a custom SpaceX-designed rack that’s lighter, denser and simpler than NVIDIA’s traditional NVL72 setup.
And these aren’t just satellites with some AI chips onboard. They’re essentially datacenters in orbit, solar-powered, running datacenter-class compute, with results beamed back to Earth through Starlink laser links.
SpaceX says the same radical rack design will also be used on the
SpaceX is reportedly taking NVIDIA’s Vera Rubin architecture to space with its new Starmind satellites.
Each satellite could pack 72 Rubin GPUs + 36 Vera CPUs into a custom SpaceX-designed rack that’s lighter, denser and simpler than NVIDIA’s traditional NVL72 setup.
And these aren’t just satellites with some AI chips onboard. They’re essentially datacenters in orbit, solar-powered, running datacenter-class compute, with results beamed back to Earth through Starlink laser links.
SpaceX says the same radical rack design will also be used on the

AMD has officially confirmed its next-generation Zen 7 and Zen 8 CPU architectures, which arrive in EPYC Florence and EPYC Ravenna chips. https://wccftech.com/amd-z...

The Galaxy Z Fold 8 series will get a new foldable display architecture, Samsung admits, which will improve the phone’s... https://9to5google.com/202...

🤖 OpenAI just hired one of the architects of modern AI.
Noam Shazeer, a legendary AI researcher and one of the key minds behind the transformer revolution, has reportedly joined OpenAI to lead AI architecture research.
If his name sounds unfamiliar, his work definitely isn’t. Shazeer co-authored the 2017 paper “Attention Is All You Need”, which introduced transformers, the breakthrough that powers ChatGPT, Gemini, Claude, and nearly every major AI model today.
His résumé is stacked: multi-head attention, Mixture-of-Experts (MoE), and T5 all trace back to ideas he helped create.
After more
Noam Shazeer, a legendary AI researcher and one of the key minds behind the transformer revolution, has reportedly joined OpenAI to lead AI architecture research.
If his name sounds unfamiliar, his work definitely isn’t. Shazeer co-authored the 2017 paper “Attention Is All You Need”, which introduced transformers, the breakthrough that powers ChatGPT, Gemini, Claude, and nearly every major AI model today.
His résumé is stacked: multi-head attention, Mixture-of-Experts (MoE), and T5 all trace back to ideas he helped create.
After more

🚀 SpaceX unveiled its AI1 satellite, the first generation of its AI satellite.
Overall Specs:
• 150 kW peak compute payload
• 120 kW average compute payload
• 70 kW per ton
• Compute provider interchangeable
Dimensions:
• Wingspan: 70 meters
• Deployed height: 20 meters
Thermal System:
• 110 m² deployable liquid radiator
• Redundant pumping loops
• Integrated micrometeoroid shielding
• Deployable liquid radiators
Solar Power System:
• 150 kW solar array
• 250 W/m²
• SpaceX-manufactured solar technology from Bastrop, Texas
Architecture:
• Centralized compute module
• Large deployable
Overall Specs:
• 150 kW peak compute payload
• 120 kW average compute payload
• 70 kW per ton
• Compute provider interchangeable
Dimensions:
• Wingspan: 70 meters
• Deployed height: 20 meters
Thermal System:
• 110 m² deployable liquid radiator
• Redundant pumping loops
• Integrated micrometeoroid shielding
• Deployable liquid radiators
Solar Power System:
• 150 kW solar array
• 250 W/m²
• SpaceX-manufactured solar technology from Bastrop, Texas
Architecture:
• Centralized compute module
• Large deployable

🔍 Google introduces Gemma 4 12B, a multimodal open model that runs on a laptop
Google has unveiled Gemma 4 12B, its latest open-weight model with advanced reasoning, vision, and audio capabilities. Despite its size, it delivers performance close to larger Gemma models while running locally on just 16GB of VRAM and is released under the permissive Apache 2.0 license.
The most interesting part is its new unified architecture.
Most multimodal models rely on separate vision and audio encoders, which add memory overhead and latency. Gemma 4 12B largely removes them:
👁 Vision: A lightweight embe
Google has unveiled Gemma 4 12B, its latest open-weight model with advanced reasoning, vision, and audio capabilities. Despite its size, it delivers performance close to larger Gemma models while running locally on just 16GB of VRAM and is released under the permissive Apache 2.0 license.
The most interesting part is its new unified architecture.
Most multimodal models rely on separate vision and audio encoders, which add memory overhead and latency. Gemma 4 12B largely removes them:
👁 Vision: A lightweight embe

🚀 MiniMax just unveiled M3, an open-weights AI model aiming to compete with the frontier labs on three of the hardest problems in AI at once.
Most models specialize in one area. M3 is trying to combine all three:
✅ Frontier-level coding and agent capabilities
✅ Massive 1 million token context window
✅ Native multimodal understanding from day one
Its benchmark results are impressive:
• 59.0% on SWE-Bench Pro
• 66.0% on Terminal Bench 2.1
• 34.8% on KernelBench Hard
• 74.2% on MCP Atlas
• 34.8% SWE-fficiency
The model is powered by MiniMax’s new Sparse Attention architecture, which allows i
Most models specialize in one area. M3 is trying to combine all three:
✅ Frontier-level coding and agent capabilities
✅ Massive 1 million token context window
✅ Native multimodal understanding from day one
Its benchmark results are impressive:
• 59.0% on SWE-Bench Pro
• 66.0% on Terminal Bench 2.1
• 34.8% on KernelBench Hard
• 74.2% on MCP Atlas
• 34.8% SWE-fficiency
The model is powered by MiniMax’s new Sparse Attention architecture, which allows i

🔥If you're not using Claude at your job, you're already behind.
Copy these 9 prompts:
1. Parallel Task Coordinator
"I have these tasks: [list them]. Handle each one fully and independently. Flag any conflicts between them as you go. Merge all outputs into one clean deliverable at the end."
2. Project Auditor
"Audit my uploaded project. Give me a prioritized list of: architecture problems, technical debt, security vulnerabilities, performance bottlenecks, and outdated dependencies. For each issue, severity, exact location, exact fix."
3. Project Context Brief
"Project: [name]. What we're
Copy these 9 prompts:
1. Parallel Task Coordinator
"I have these tasks: [list them]. Handle each one fully and independently. Flag any conflicts between them as you go. Merge all outputs into one clean deliverable at the end."
2. Project Auditor
"Audit my uploaded project. Give me a prioritized list of: architecture problems, technical debt, security vulnerabilities, performance bottlenecks, and outdated dependencies. For each issue, severity, exact location, exact fix."
3. Project Context Brief
"Project: [name]. What we're
🇨🇳 DeepSeek just open-sourced a 1.6T AI model built for coding agents and million-token memory
DeepSeek unveiled its V4 generation with two new foundation models: DeepSeek-V4-Pro (1.6 trillion parameters, activating only 49B per token) and DeepSeek-V4-Flash (284B parameters focused on efficiency). The release pushes open-source AI closer to the frontier dominated by closed labs.
What makes V4 different:
• Introduces DeepSeek Sparse Attention (DSA), a new architecture designed to cut memory and compute costs.
• Uses token-wise compression, allowing far longer context windows without the usua
DeepSeek unveiled its V4 generation with two new foundation models: DeepSeek-V4-Pro (1.6 trillion parameters, activating only 49B per token) and DeepSeek-V4-Flash (284B parameters focused on efficiency). The release pushes open-source AI closer to the frontier dominated by closed labs.
What makes V4 different:
• Introduces DeepSeek Sparse Attention (DSA), a new architecture designed to cut memory and compute costs.
• Uses token-wise compression, allowing far longer context windows without the usua
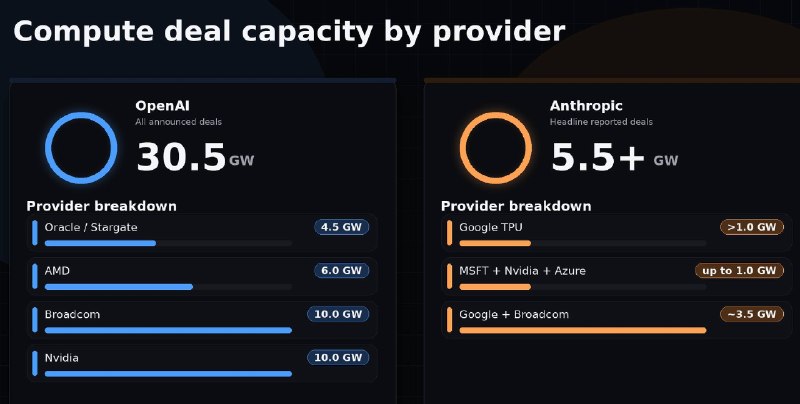
Right now, compute is everything..
Anthropic does not have enough of it, which is why opus performance is degrading.
OpenAI felt the pressure in 2025, especially after the Ghibli wave, which pushed sam to lock in long-term compute. Until there is a breakthrough in model architecture or chip design, this cycle will continue.
aipost 🏴
Anthropic does not have enough of it, which is why opus performance is degrading.
OpenAI felt the pressure in 2025, especially after the Ghibli wave, which pushed sam to lock in long-term compute. Until there is a breakthrough in model architecture or chip design, this cycle will continue.
aipost 🏴
⚡️ Runway has unveiled a massive breakthrough in AI video generation at NVIDIA's GTC event, showcasing a new model capable of generating high-definition video in genuine real-time.
The new model boasts a "time-to-first-frame" of under 100 milliseconds. This means HD video begins generating and playing almost the instant a command is given.
This research preview was co-developed with NVIDIA and runs on their newly announced Vera Rubin architecture. This real-time capability is a foundational step for Runway's General World Model (GWM-1). It pushes the technology beyond simple video generation
The new model boasts a "time-to-first-frame" of under 100 milliseconds. This means HD video begins generating and playing almost the instant a command is given.
This research preview was co-developed with NVIDIA and runs on their newly announced Vera Rubin architecture. This real-time capability is a foundational step for Runway's General World Model (GWM-1). It pushes the technology beyond simple video generation

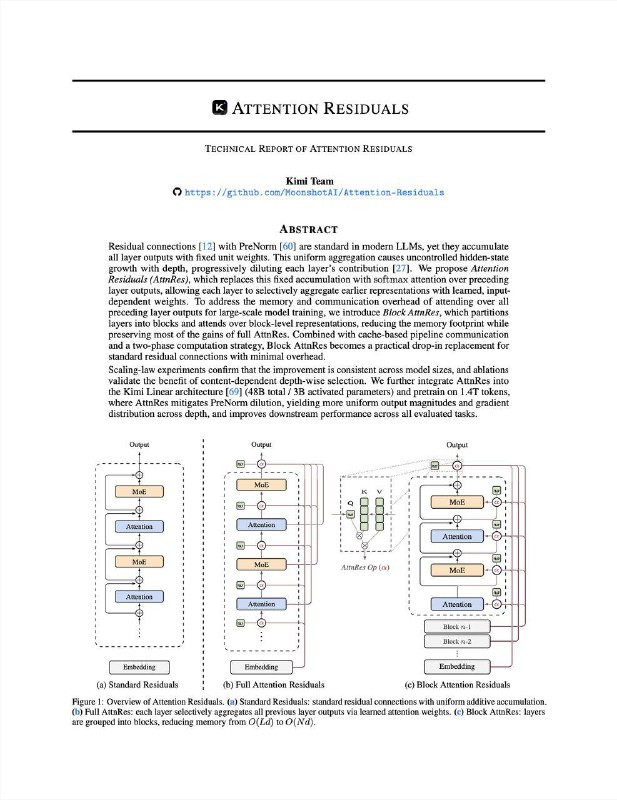
🔥 Kimi AI introduces Attention Residuals, a new way to rethink how neural networks use past layers
Researchers at Moonshot AI just proposed a new architecture tweak that could make large AI models more efficient and smarter about how they use information from earlier layers. Instead of the traditional residual connections used in deep networks, they introduce Attention Residuals, a system where each layer can selectively attend to representations from previous layers.
Here’s what’s new:
Attention over past layers:
• Traditional residuals simply add outputs from earlier layers in a fixed way
Researchers at Moonshot AI just proposed a new architecture tweak that could make large AI models more efficient and smarter about how they use information from earlier layers. Instead of the traditional residual connections used in deep networks, they introduce Attention Residuals, a system where each layer can selectively attend to representations from previous layers.
Here’s what’s new:
Attention over past layers:
• Traditional residuals simply add outputs from earlier layers in a fixed way
🔥 Kimi AI introduces Attention Residuals, a new way to rethink how neural networks use past layers Researchers at Moonshot AI just proposed a new architecture tweak that could make large AI models more efficient and smarter about how they use information…
⚡️NVIDIA unveiled its first AI supercomputer integrating Groq racks alongside the Vera Rubin platform.
The system combines Rubin GPUs for memory-heavy workloads with Groq’s architecture for fast token generation to reduce inference latency and scale AI factories.
aipost 🏴
The system combines Rubin GPUs for memory-heavy workloads with Groq’s architecture for fast token generation to reduce inference latency and scale AI factories.
aipost 🏴
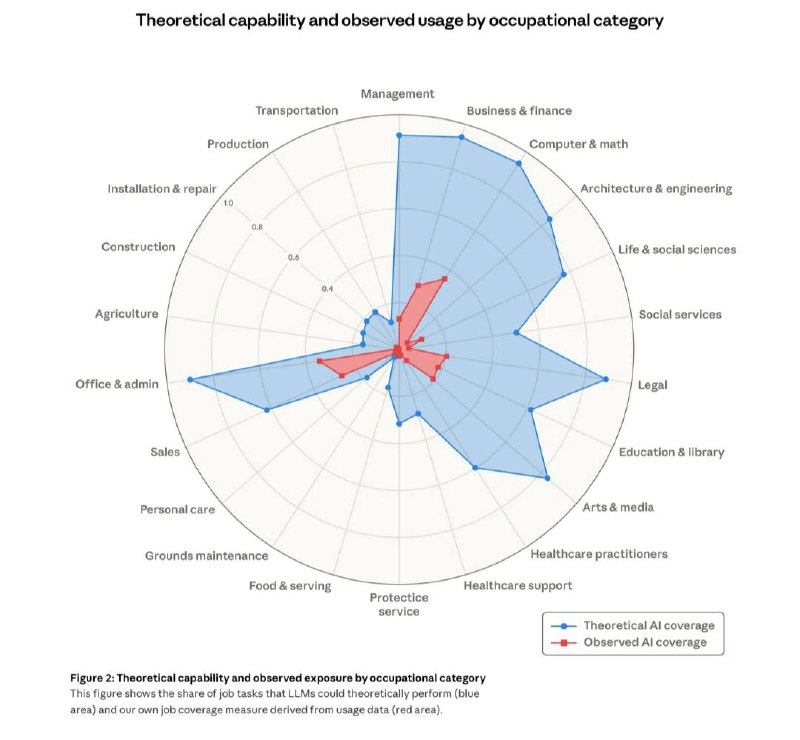
⚠️Anthropic just studied which jobs AI can theoretically replace vs. which ones it's actually automating right now.
Computer & math: 94% exposed. Legal: ~90%. Management, architecture, arts & media: all 60%+. Observed usage so far? A fraction of that.
But the gap is closing fast. Every field where the blue line towers over the red is borrowed time. Grounds maintenance and construction are sitting at near-zero on both.
Might be a good year to learn landscaping!
https://www.anthropic.com/...
aipost 🏴
Computer & math: 94% exposed. Legal: ~90%. Management, architecture, arts & media: all 60%+. Observed usage so far? A fraction of that.
But the gap is closing fast. Every field where the blue line towers over the red is borrowed time. Grounds maintenance and construction are sitting at near-zero on both.
Might be a good year to learn landscaping!
https://www.anthropic.com/...
aipost 🏴
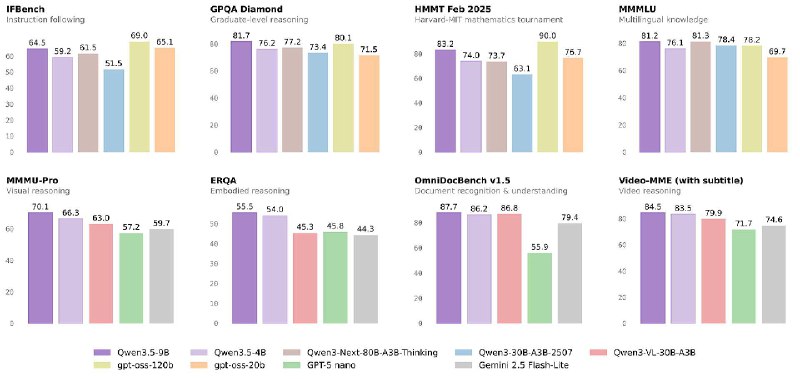
🚀 Alibaba group expands Qwen3.5 with ultra-efficient small models
Alibaba has introduced the Qwen 3.5 Small Model Series, a new lineup designed to deliver stronger intelligence with significantly lower compute requirements.
The release includes four compact models: Qwen3.5-0.8B · Qwen3.5-2B · Qwen3.5-4B · Qwen3.5-9B
Built on the Same Qwen3.5 Foundation
All models inherit the core architecture of the Qwen3.5 family:
• Native multimodal capabilities
• Improved model architecture
• Scaled reinforcement learning (RL) training
• Better efficiency per parameter
This isn’t a stripped-down versio
Alibaba has introduced the Qwen 3.5 Small Model Series, a new lineup designed to deliver stronger intelligence with significantly lower compute requirements.
The release includes four compact models: Qwen3.5-0.8B · Qwen3.5-2B · Qwen3.5-4B · Qwen3.5-9B
Built on the Same Qwen3.5 Foundation
All models inherit the core architecture of the Qwen3.5 family:
• Native multimodal capabilities
• Improved model architecture
• Scaled reinforcement learning (RL) training
• Better efficiency per parameter
This isn’t a stripped-down versio
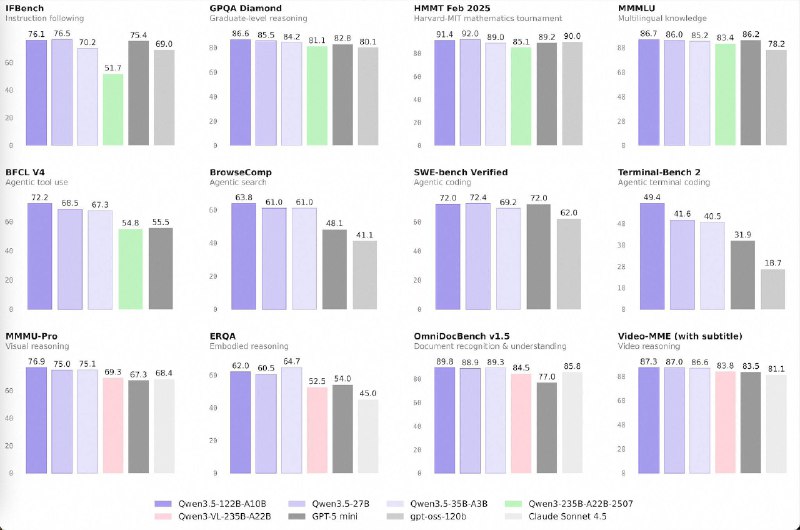
🚀 Qwen 3.5: Frontier intelligence without frontier size
Alibaba Group just released the Qwen 3.5 Medium model series and it’s a clear signal that smarter architecture is beating brute-force scale.
Lineup:
• Qwen3.5-Flash
• Qwen3.5-35B-A3B
• Qwen3.5-122B-A10B
• Qwen3.5-27B
What changed?
• 35B-A3B now outperforms previous 235B-class Qwen 3 models. Smaller model. Better results. Architecture + data quality + RL > raw parameter count.
• 122B and 27B are closing the gap between medium-sized models and frontier systems — especially in multi-step agent workflows.
This is the “efficiency era” of A
Alibaba Group just released the Qwen 3.5 Medium model series and it’s a clear signal that smarter architecture is beating brute-force scale.
Lineup:
• Qwen3.5-Flash
• Qwen3.5-35B-A3B
• Qwen3.5-122B-A10B
• Qwen3.5-27B
What changed?
• 35B-A3B now outperforms previous 235B-class Qwen 3 models. Smaller model. Better results. Architecture + data quality + RL > raw parameter count.
• 122B and 27B are closing the gap between medium-sized models and frontier systems — especially in multi-step agent workflows.
This is the “efficiency era” of A
🚀 Qwen3.5-397B-A17B: Open-Weight, Multimodal, Agent-Ready
Alibaba’s Qwen team just released the first open-weight model in the Qwen3.5 series built specifically for real-world AI agents.
What stands out:
• Native multimodal, text + image understanding out of the box
• Hybrid linear attention + sparse MoE architecture
• Large-scale RL environment scaling
• 8.6x–19.0x faster decoding vs Qwen3-Max
• Supports 201 languages & dialects
• Apache 2.0 license
Open weights + high throughput + permissive licensing = serious pressure on closed model providers.
Dive in:
• GitHub: https://github.com/Qw
Alibaba’s Qwen team just released the first open-weight model in the Qwen3.5 series built specifically for real-world AI agents.
What stands out:
• Native multimodal, text + image understanding out of the box
• Hybrid linear attention + sparse MoE architecture
• Large-scale RL environment scaling
• 8.6x–19.0x faster decoding vs Qwen3-Max
• Supports 201 languages & dialects
• Apache 2.0 license
Open weights + high throughput + permissive licensing = serious pressure on closed model providers.
Dive in:
• GitHub: https://github.com/Qw
UK-based startup 'Humanoid' announced KinetIQ, an AI framework with a Vision-Language-Action (VLA) model at its core.
It uses a four-layer architecture: fleet orchestration, task decomposition, VLA, and RL for whole-body control. It works on both bipedal and wheeled robots.
aipost 🏴
It uses a four-layer architecture: fleet orchestration, task decomposition, VLA, and RL for whole-body control. It works on both bipedal and wheeled robots.
aipost 🏴
⚡️NVIDIA just removed the biggest friction point in Voice AI
They've open-sourced PersonaPlex-7B, a full-duplex conversational model that can listen and speak at the same time.
Instead of waiting for you to finish talking, it uses a dual-stream architecture to process and respond in real-time. 100% Open-Source and Free.
https://github.com/NVIDIA/...
aipost 🏴
They've open-sourced PersonaPlex-7B, a full-duplex conversational model that can listen and speak at the same time.
Instead of waiting for you to finish talking, it uses a dual-stream architecture to process and respond in real-time. 100% Open-Source and Free.
https://github.com/NVIDIA/...
aipost 🏴
The US moat is melting, Demis Hassabis, the CEO of Google DeepMind told CNBC.
"China's artificial intelligence models may be just "a matter of months" behind U.S. and Western capabilities.
Chinese AI models are closer to U.S. and Western capabilities "than maybe we thought one or two years ago." The only thing China still lacks is the ability to explore its own breakthroughs, such as Transformer architecture. For now.
aipost 🏴
"China's artificial intelligence models may be just "a matter of months" behind U.S. and Western capabilities.
Chinese AI models are closer to U.S. and Western capabilities "than maybe we thought one or two years ago." The only thing China still lacks is the ability to explore its own breakthroughs, such as Transformer architecture. For now.
aipost 🏴

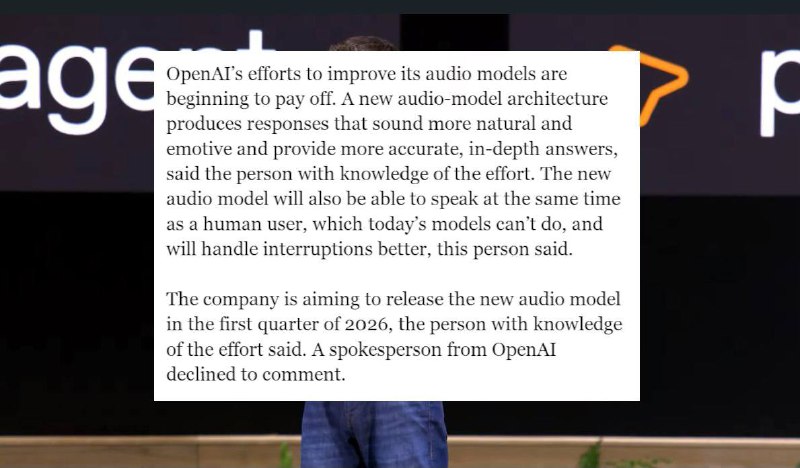
📢 OpenAI is preparing to release a new audio model in connection with its upcoming standalone audio device!
OpenAI is aggressively upgrading its audio AI to power a future audio-first personal device, expected in about a year. Internal teams have merged, a new voice model architecture is coming in Q1 2026, and early gains include more natural, emotional speech, faster responses, and real-time interruption handling - key for a companion-style AI that proactively helps users.
Source.
aipost 🏴
OpenAI is aggressively upgrading its audio AI to power a future audio-first personal device, expected in about a year. Internal teams have merged, a new voice model architecture is coming in Q1 2026, and early gains include more natural, emotional speech, faster responses, and real-time interruption handling - key for a companion-style AI that proactively helps users.
Source.
aipost 🏴
🗣Geoffrey Hinton says there's still major progress left just from better engineering, not just new science
DeepSeek is a clear example: smarter training and more efficient use of older NVIDIA chips can deliver strong results with less compute and energy. "We'll see new architectures we haven't even imagined yet"
aipost 🏴
DeepSeek is a clear example: smarter training and more efficient use of older NVIDIA chips can deliver strong results with less compute and energy. "We'll see new architectures we haven't even imagined yet"
aipost 🏴

🗣Sergey Brin admits Google messed up by under-investing in the transformer architecture it invented
Google was too scared to release chatbots that "say dumb things", so it under-invested in scaling compute. "We didn't take it very seriously... and openAI ran with it"
AI Post ⚪️ | Our X 🏴
Google was too scared to release chatbots that "say dumb things", so it under-invested in scaling compute. "We didn't take it very seriously... and openAI ran with it"
AI Post ⚪️ | Our X 🏴

Cybersecurity researchers have uncovered a critical vulnerability in the architecture of large language models underpinning generative AI, but how dangerous is this flaw? https://www.livescience.co...
🔔 Big breakthrough in scientific reasoning
New AI system - SciAgent exceeds human gold medalists on several Science Olympiads, using one unified architecture.
There are no discipline specific modules. Just pure cross domain scientific reasoning. The implications for research automation and multi domain AI reasoning are enormous.
AI Post 🪙 | Our X 🥇
New AI system - SciAgent exceeds human gold medalists on several Science Olympiads, using one unified architecture.
There are no discipline specific modules. Just pure cross domain scientific reasoning. The implications for research automation and multi domain AI reasoning are enormous.
AI Post 🪙 | Our X 🥇

Huge AI news from Google
Google Research just unveiled a bold new ML paradigm that views a model as a stack of nested problems so it can keep learning new skills forever without forgetting the old ones, a huge leap toward AI that actually evolves like a brain.
On tests of language modeling, long context reasoning and continual learning, Hope (self modifying architecture) outperformed traditional transformer architectures and older methods.
Big progress
Details. Paper.
AI Post 🪙 | Our X 🥇
Google Research just unveiled a bold new ML paradigm that views a model as a stack of nested problems so it can keep learning new skills forever without forgetting the old ones, a huge leap toward AI that actually evolves like a brain.
On tests of language modeling, long context reasoning and continual learning, Hope (self modifying architecture) outperformed traditional transformer architectures and older methods.
Big progress
Details. Paper.
AI Post 🪙 | Our X 🥇

При финансовой поддержке
Vitali Dogot
1 год назад
RelaxM – Мебель для вашего дома“
RelaxM — мебель, которая создаёт уют в вашем доме. Мы предлагаем качественные столы и стулья из прочных материалов. Изысканный дизайн, комфорт и долговечность.