Does a sound card really improve audio quality on a PC? For most uses, the improvement won't be noticeable. But those who require high-precision audio need it. https://www.engadget.com/2...
Xiaomi has launched MiMo-V2.6-Pro, which now ranks at the top of open-weight models on the Artificial Analysis Intelligence Index. The model scored 46 points, just behind GPT-5.6 Sol (max) at 47, according to AA Benchmarks.
There is a significant cost difference per Intelligence Index task: $0.13 for MiMo-V2.6-Pro compared to $1.99 for GPT-5.6 Sol (max), based on a weighted-average measure.
MiMo-V2.6-Pro supports text, image, video, and audio input within a 1 million-token context window. API pricing remains unchanged from the V2.5 version.
Model weights have been released under the MIT lic

The two companies have entered into a multi-year partnership. Motorola saw what Poco (and, before it, Redmi in China) did with Bose, and thought it wanted... https://www.gsmarena.com/t...
Belkin's UltraCharge Power Bank, Wireless Microphone, Magnetic Charging Camera Grip, RockStar USB-C Audio Adapter, and Magnetic Wireless Power Bank w/ Stand. https://www.bgr.com/225309...
The company claims reports about its capturing and uploading audio are misleading. https://www.theverge.com/t...

Recent accusations against the electronics company have raised new questions about the nonconsensual data it harvests. https://www.aljazeera.com/...

An investigation by Gamers Nexus found LG smart TVs sweep local networks to map phones and nearby devices. Tests also showed the sets can capture microphone audio with the screen off — they then upload data once reconnected to the internet. https://www.notebookcheck....
Infinity Ward has deployed the first proper update to the Warfare 4 beta, addressing much of the feedback from the beta's opening day. https://www.eurogamer.net/...

Anker owns Anker Solix, AnkerWork, Eufy, Soundcore, and Nebula, covering portable power, office gear, smart homes, audio, and projectors. https://www.slashgear.com/...
❗️Google DeepMind launched SL2T (Sign Language to Text), an AI model that translates sign language directly into text.
Most spoken language dictation tools rely on audio to text, but sign languages have their own grammars and involve complex 3D movements. Instead of using raw camera feeds or physical gloves, SL2T tracks body landmark coordinates locally with MediaPipe Holistic and translates those spatial points into text.
Users can sign naturally to search, draft messages, or respond in live conversations instead of typing everything out.
aipost 🏴

Bose owns more than its own speakers and headphones. Here are three premium audio brands now under its umbrella following a major acquisition. https://www.bgr.com/222866...
🎤 OpenAI reveals the secret behind GPT-Live’s natural voice conversations
OpenAI has shared how GPT-Live delivers conversations that feel surprisingly human.
Instead of waiting for you to stop talking, GPT-Live uses continuous audio, meaning it listens and speaks at the same time for a smoother, more natural flow.
Complex reasoning and tool calls happen in the background while a faster model keeps the conversation going, so you don’t experience awkward pauses.
OpenAI also rebuilt much of its voice infrastructure in Go, significantly reducing latency. The company says the new system’s slowe

Ozlo’s first major update to its sleep earbuds introduces longer battery life, improved connectivity, enhanced audio, and new sleep features as the startup continues the product line once abandoned by Bose. https://techcrunch.com/202...

Over the past decade, streaming platforms competed by dominating individual formats like music, video, podcasts, or audiobooks. Now, as AI makes it easier to create, organize, and recommend content, those distinctions are fading, pushing companies like Spotify, Netflix, YouTube, and TikTok to become all-purpose entertainment destinations instead. https://techcrunch.com/202...


Vă așteptăm la bordul troleibuzului turistic! Programul curselor de sâmbătă și duminică este următorul: 1️⃣ rută: ora 12:00 (audioghid în l. rusă) 2️⃣ rută: ora 14:00 (audioghid în l. engleză) 3️⃣ rută: ora 16:00 (audioghid în l. română) ????Startul – Arcul de Triumf Capacitatea de îmbarcare în troleibuzul turistic este permisă în limita a 22 de persoane, așezate pe scaune, iar copii până la 7 ani, în mod obligatoriu, urmează a fi însoțiți de un părinte. Prețul pentru o călătorie cu troleibuzul turistic constituie – 30 lei. ❤️Lansarea Troleibuzului Turistic – Chișinău Sightseeing are drept

🗣A Robotic mouth tries to speak like a human
Instead of using digital audio, this artificial mouth physically recreates speech with an air pump for lungs, silicone for a tongue, and eight artificial vocal cords. Impressive, weird, and slightly terrifying from Japan.
aipost 🏴
Instead of using digital audio, this artificial mouth physically recreates speech with an air pump for lungs, silicone for a tongue, and eight artificial vocal cords. Impressive, weird, and slightly terrifying from Japan.
aipost 🏴

🔍 Google introduces Gemma 4 12B, a multimodal open model that runs on a laptop
Google has unveiled Gemma 4 12B, its latest open-weight model with advanced reasoning, vision, and audio capabilities. Despite its size, it delivers performance close to larger Gemma models while running locally on just 16GB of VRAM and is released under the permissive Apache 2.0 license.
The most interesting part is its new unified architecture.
Most multimodal models rely on separate vision and audio encoders, which add memory overhead and latency. Gemma 4 12B largely removes them:
👁 Vision: A lightweight embe

🔥Microsoft unveils MAI-Voice-2, pushing AI voices closer to human speech
Microsoft has introduced Microsoft MAI-Voice-2 and MAI-Voice-2-Flash, its latest text-to-speech models designed to generate more natural, expressive, and multilingual voices.
🔹MAI-Voice-2
• Focused on high-quality speech generation.
• Better emotional expression and voice control.
• More consistent long-form narration for audiobooks, podcasts, and assistants.
• Supports multiple languages and speaking styles
⚡ MAI-Voice-2-Flash
• Optimized for low-latency, real-time applications
• Built for AI agents, voice assistan

Leaked audio from a Meta all-hands on April 30:
Zuckerberg told employees the company is using them to train AI models before mass layoffs hit.
His argument? Meta's engineers are smarter than any external workforce, so having them solve coding tasks internally will make Meta's models better, faster than competitors. The layoffs are expected Wednesday at 4 am.
Train your replacement, then get walked out. That's the deal now.
aipost 🏴
🧠 Thinking Machines is replacing turn-based AI with always-present AI.
They just unveiled TML-Interaction-Small, a 276B-parameter MoE model built for continuous real-time interaction instead of stop-start conversations.
Most AI voice systems still work like walkie-talkies: you talk → they stop listening → they answer.
Thinking Machines slices audio, video, and text into 200ms micro-turns, letting the model:
• listen while speaking
• react to gestures and screen changes
• interrupt naturally when needed
• track silence and timing
• call tools in the background without leaving the conversati

🐾 A surprisingly lifelike robot pet is coming
Colin Angle is back with a new company, Familiar Machines & Magic, and its first creation: a four-legged companion robot called Familiar.
Instead of screens or speech-first interaction, the robot communicates through movement, sound, and touch. It has 23 degrees of freedom, a full-body tactile “skin,” cameras, and microphones, allowing it to react to context, remember interactions, and adapt its behavior to its owner over time.
What stands out is that all the AI runs locally on the device, processing video, audio, and memory in real time without

🔥 Google DeepMind launched Gemini 3.1 Flash TTS, a text-to-speech model for precise audio control.
Its "Audio Tags" feature lets users set vocal style, emotion, and pacing via text. Supporting over 70 languages with native SynthID watermarking, the model is available in preview on the Gemini API and Google AI Studio, rolling out to enterprises on Vertex AI, and integrating into Google Vids for consumers.
Source.
aipost 🏴

Google released Gemma 4, an open model family for reasoning and agentic workflows. 🚀
Key features:
- Four sizes: E2B/E4B for edge devices (phones, Raspberry Pi, Jetson Nano); 26B MoE and 31B Dense for single cloud GPUs or workstations.
- Enhanced multi-step reasoning, math, and instruction-following.
- Native function-calling, JSON output, and system instructions for agentic workflows.
- Integrated vision/video (OCR, charts, variable resolution) across all models.
- Audio input for speech recognition on E2B/E4B. 🎤
- High-quality offline code generation. 💻
- 140+ languages. 🌍
- 128K context (
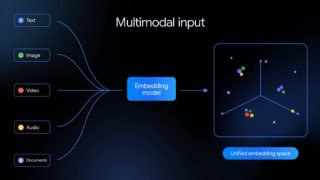
🔥 Google dropped Gemini Embedding 2
One model. Text, images, video, audio, PDFs... same vector space.
Source.
aipost 🏴
One model. Text, images, video, audio, PDFs... same vector space.
Source.
aipost 🏴
📢 OpenAI developing real-time conversational audio
OpenAI is building a new bidirectional (BiDi) audio model designed to make AI conversations feel far more natural. Unlike today’s turn-based voice systems - where the AI waits for you to finish and can’t adjust mid-response - BiDi continuously processes speech, allowing it to adapt instantly if users interrupt or change direction.
The prototype still glitches after a few minutes, delaying launch from the expected Q1 timeline to potentially Q2 or later, but the upgrade could significantly improve customer support bots, voice assistants, and s
🎬 Kling 3.0 turns text into cinematic, full-stack video production
Kling just rolled out Kling 3.0, its most powerful model yet positioned as a native multimodal creation stack that lets anyone act like a director, end to end.
What’s new:
• High-realism video with customizable 15s clips
• Consistent characters across multiple shots and scenes
• Multi-language audio with support for different accents
• 4K image generation with cinematic visual quality
Early access is live for Ultra subscribers on the web
Kling isn’t just improving generation quality, it’s bundling video, image, and audio in
🔥 Everyone talks about AI. Very few know which tools actually matter.
1. ChatGPT – ask anything
2. RecCloud – change voice
3. Krea ai – create logos
4. ElevenLabs – voice cloning
5. Gamma app – design documents
6. Suno ai – make music
7. Runway ml – edit videos
8. Relume - web design
9. Descript – edit audio
10. Tome app – presentations
11. Perplexity ai – research
12. PicWish – edit photos
13. LumaLabs ai – 3D models
14. Pika art – AI videos
SAVE THIS
aipost 🏴
❗️New leaks to OpenAIs upcoming device:
- It’s a new audio wearable, meant to replace AirPods. (aligns with The Informations leaks)
- Codename: Sweetpea.
- Look: metal “eggstone” + two little capsules behind the ear.
- Tech: aiming for 2nm chip + maybe a custom chip for phone-like actions.
- Big ambition: 40–50M units in year one.
This is part of a broader hardware initiative, with Foxconn reportedly preparing for 5 total devices by Q4 2028, including a home-style device and a pen.
aipost 🏴

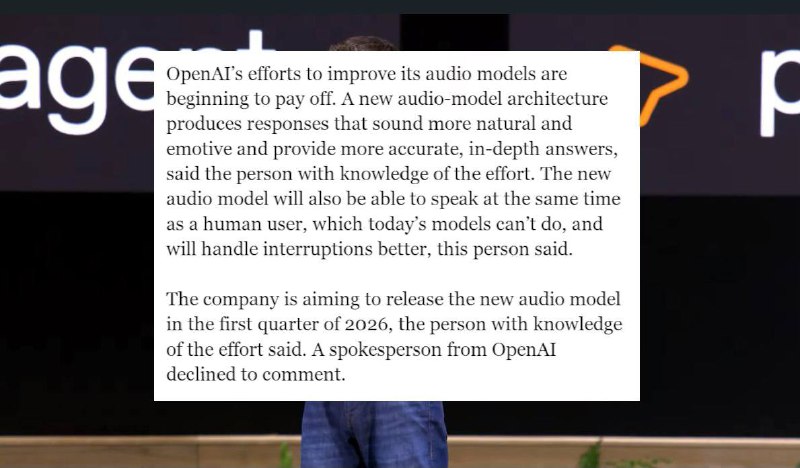
📢 OpenAI is preparing to release a new audio model in connection with its upcoming standalone audio device!
OpenAI is aggressively upgrading its audio AI to power a future audio-first personal device, expected in about a year. Internal teams have merged, a new voice model architecture is coming in Q1 2026, and early gains include more natural, emotional speech, faster responses, and real-time interruption handling - key for a companion-style AI that proactively helps users.
Source.
aipost 🏴
🚨 Google releases Gemini 3 Flash, a high-speed AI model at less than a quarter the cost of Gemini 3 Pro.
- Builds on multimodal, coding, and agentic strengths of Gemini 3 Pro, surpassing Gemini 2.5 Pro in many benchmarks with up to 3x faster performance.
- Advanced visual and spatial reasoning with code execution for tasks like zooming, counting, or editing images; supports audio inputs at $1 per million input tokens.
- Excels in PhD-level reasoning with 90.4% on GPQA Diamond and agentic coding with 78% on SWE-bench Verified.
- Context caching offers up to 90% cost savings on repeated tokens;

При финансовой поддержке
Vitali Dogot
1 год назад
RelaxM – Мебель для вашего дома“
RelaxM — мебель, которая создаёт уют в вашем доме. Мы предлагаем качественные столы и стулья из прочных материалов. Изысканный дизайн, комфорт и долговечность.